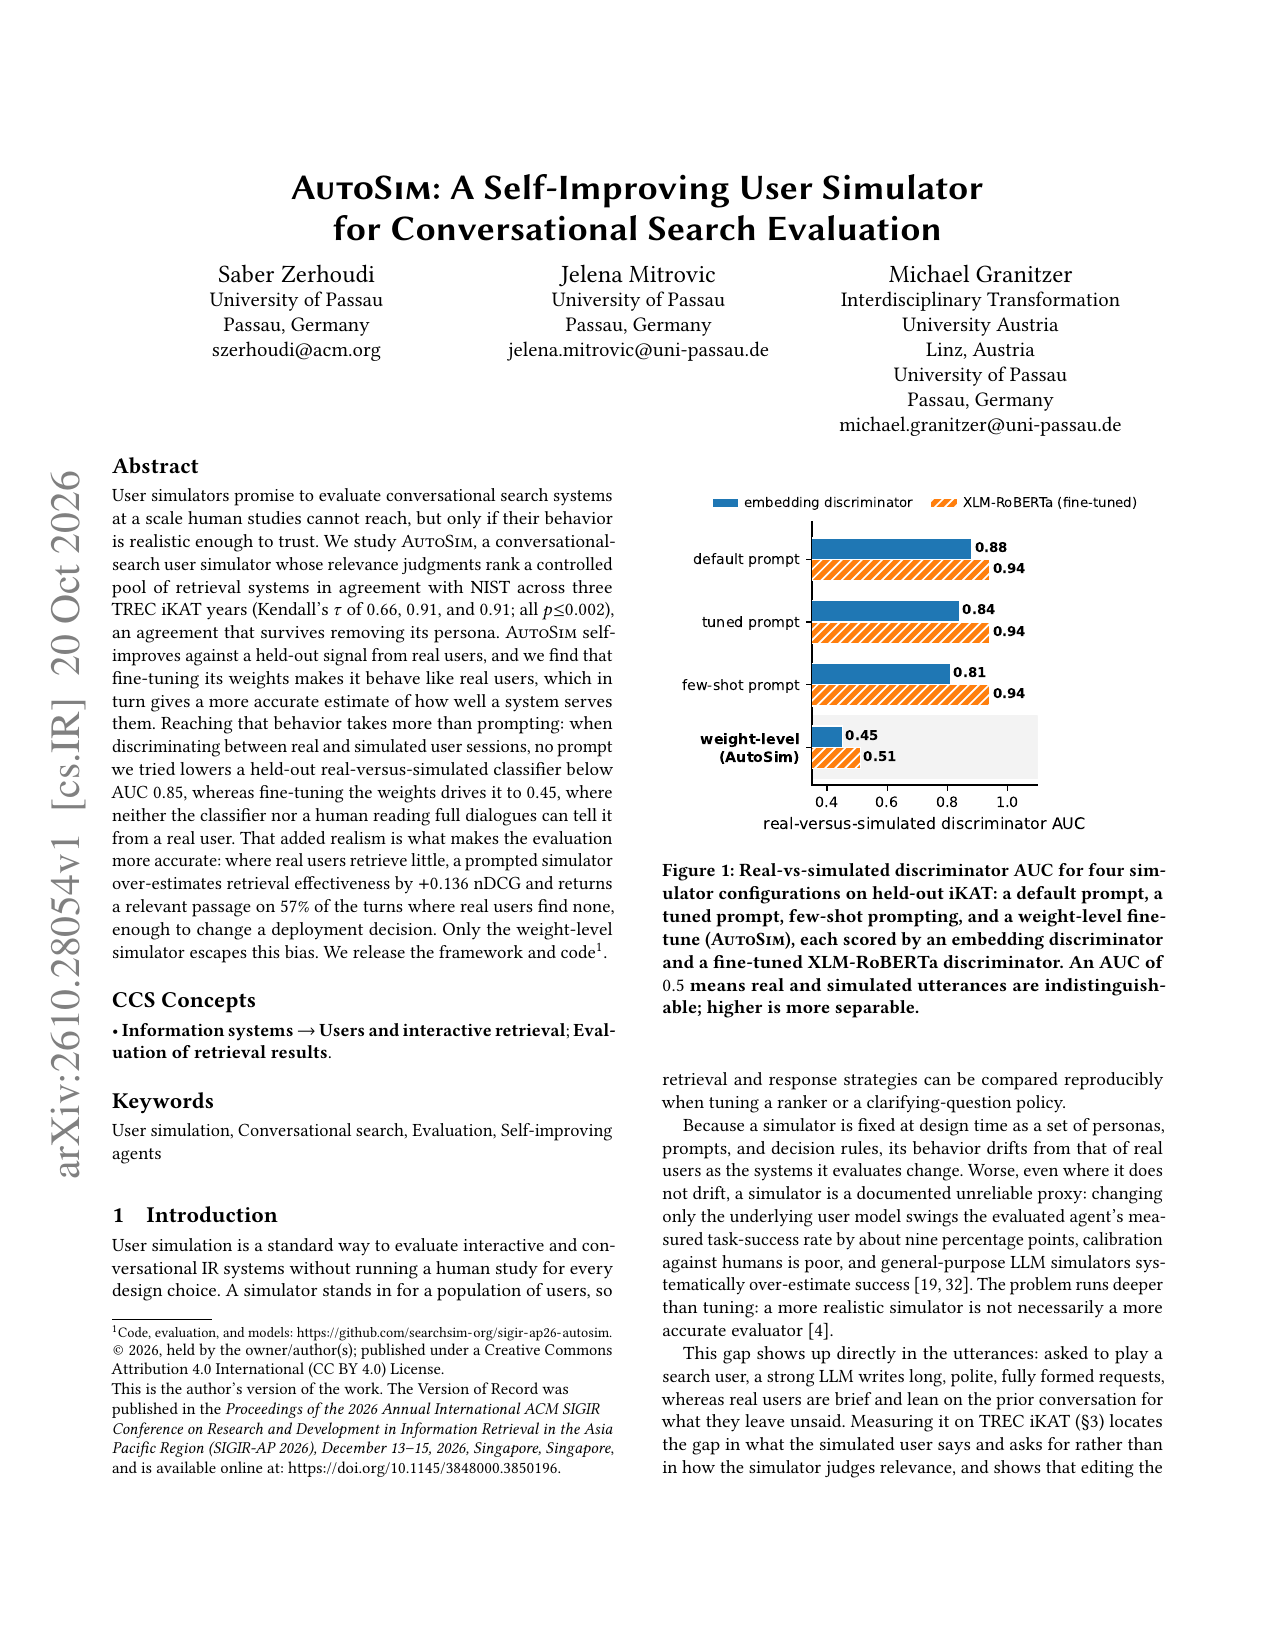
Conversational search needs trustworthy simulators. AutoSim’s relevance judgments rank a controlled pool with NIST across three TREC iKAT years (Kendall τ 0.66/0.91/0.91, all p≤0.002), surviving persona removal. Self-improving on held-out real users, weight-level updates drive real-vs-sim AUC from ~0.85 to 0.45, lift retrieval +0.136 nDCG, and return a relevant passage on 57% of turns. Trust a simulator when it ranks systems like NIST, not when it merely sounds human.
1. Problem
Prompted sims can sound human while system rankings drift. Need indistinguishability plus NIST-aligned rankings.
2. Method
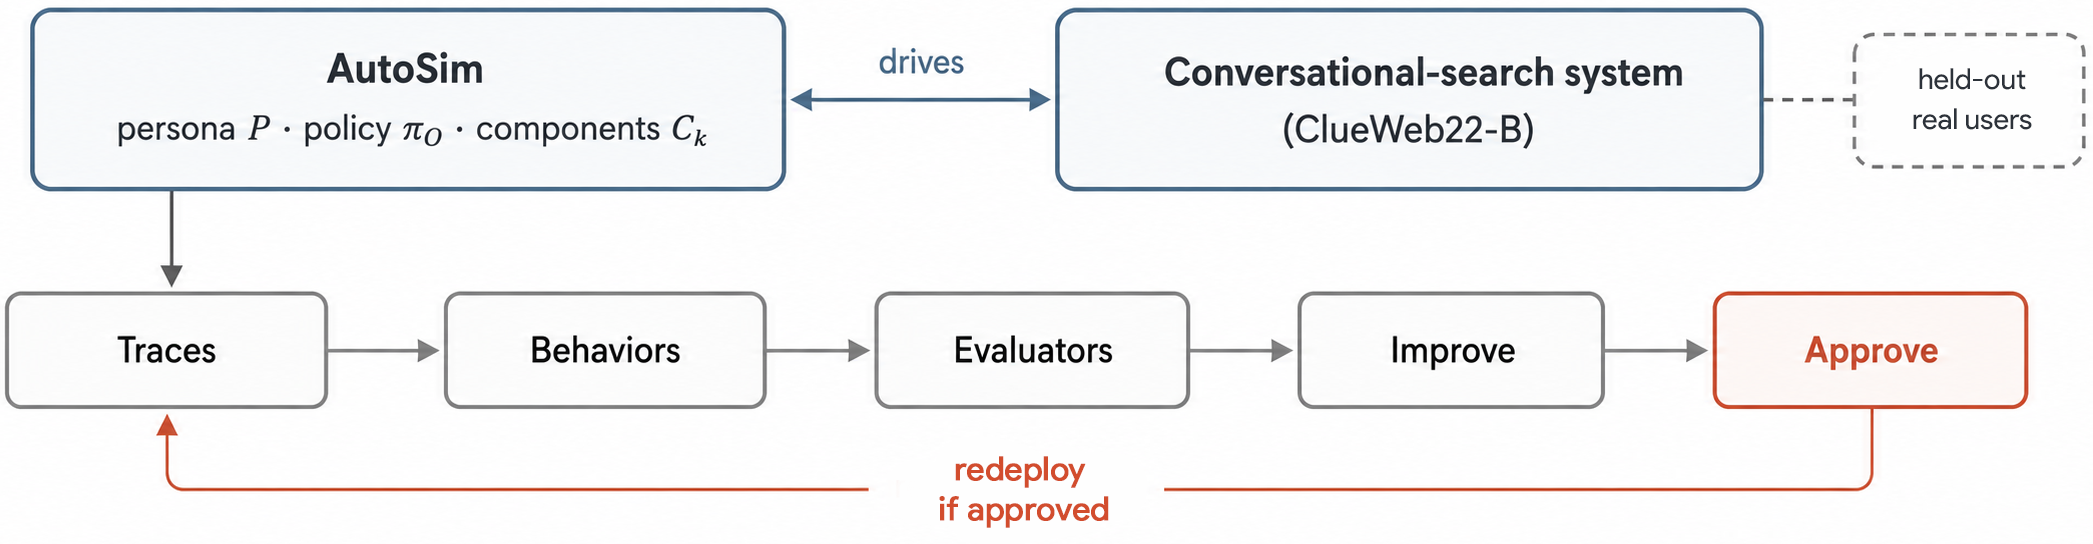
AutoSim issues queries, reads results, labels relevance; self-improves from held-out human signal (prompt vs weights). Rank real systems by condensed nDCG@5 and report Kendall τ vs NIST.
3. Core claim
Acceptance moves from fooling a classifier to ranking alignment. AUC→0.5 means fluent; τ alignment means usable eval.
4. Experiments
τ 0.66/0.91/0.91 across three iKAT years; weight self-improve → AUC 0.45, +0.136 nDCG, 57% relevant-passage turns.
5. Limits
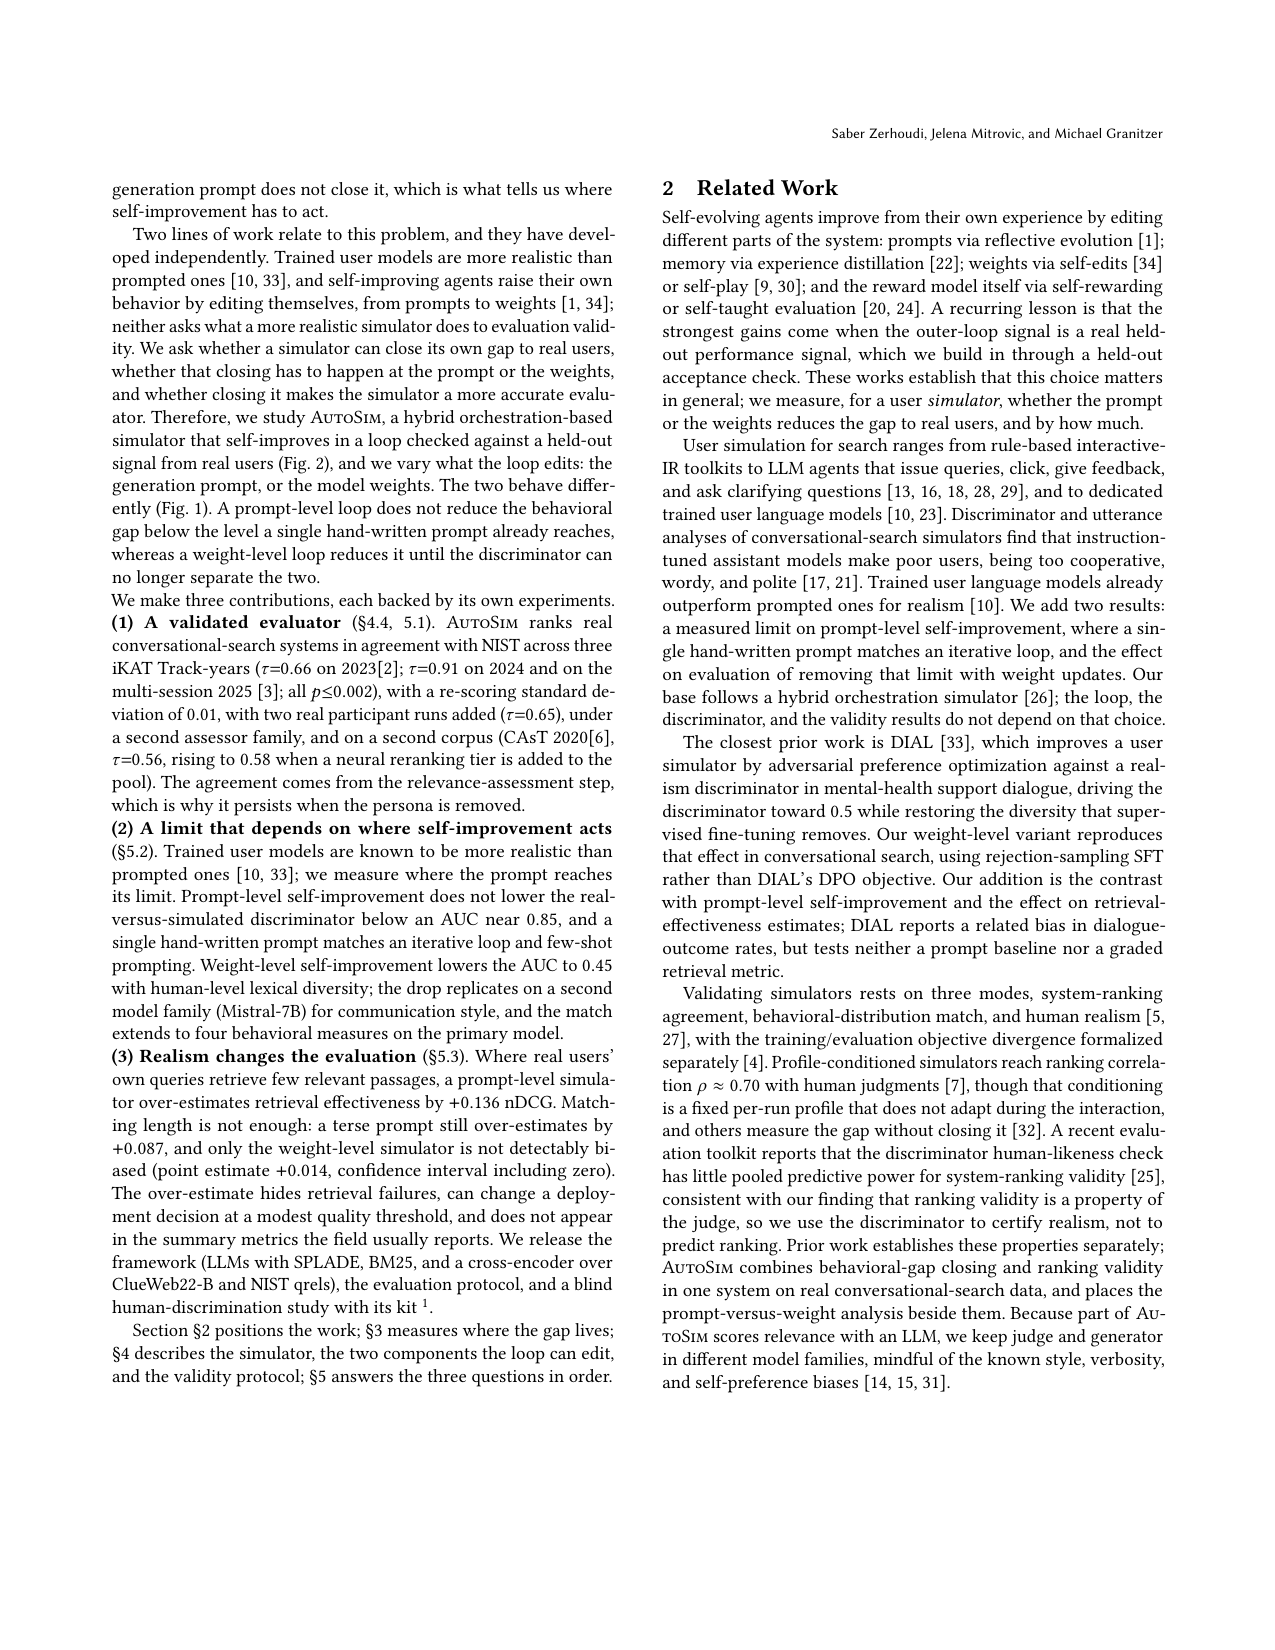
Controlled system pool; year-1 τ lower; needs held-out human signal.
6. Practice
Use sims for daily conversational-search regression; keep a small NIST/human anchor for τ.