When a large language model serves as a recommendation foundation model, one approach is to have the model first write a natural-language reasoning trace (CoT) and then output the semantic ID (SID, an identifier that maps an item to a three-level discrete code) of the next item. The reasoning text is far longer than a three-level SID, so it holds back both decoding time and throughput; moreover, earlier work on OneReason already reported that reasoning first and then answering does not consistently beat answering directly with the same model. Kuaishou's OneLatent appends 3 fixed special tokens after the user context and trains in several steps: first the model learns to reproduce a teacher LLM's reasoning text after these 3 tokens, then it is switched to outputting the target SID directly after them; at serving time only these 3 tokens are appended and no reasoning text is generated. On Kuaishou's local-services industrial data, OneLatent reaches SID@64 of 0.1993, 17.44% higher than OneReason-CoT in reason-then-answer mode, and its inference throughput is 17.49 times that of explicit reasoning, essentially the same as direct prediction without reasoning. Against the strongest baseline trained on the same teacher reasoning data and answering directly, the 3 latent tokens add only 1.58% on the industrial data, which shows that most of the gain comes from the teacher reasoning data itself. An online A/B test on 5% of traffic estimates a 9.6% revenue lift, and the model is now serving all traffic.
1. Why explicit reasoning works poorly in recommendation
The input of a foundation recommendation model (FRM) is the user profile , the chronologically ordered interaction history and the request-time context (time, location, search terms and so on); the output is the SID of the next item the user interacts with. Making the model write reasoning first causes two problems. One is cost: every request must decode the whole reasoning text token by token. The other is that accuracy does not necessarily rise: an extra generation path sits between the reasoning text and the SID, and if the reasoning goes off by one step, the SID that follows goes off with it. In the paper's Table 2, OneReason-CoT in reason-first mode reaches SID@64 of 0.1697 on the industrial data, below the 0.1823 of the same checkpoint answering directly.
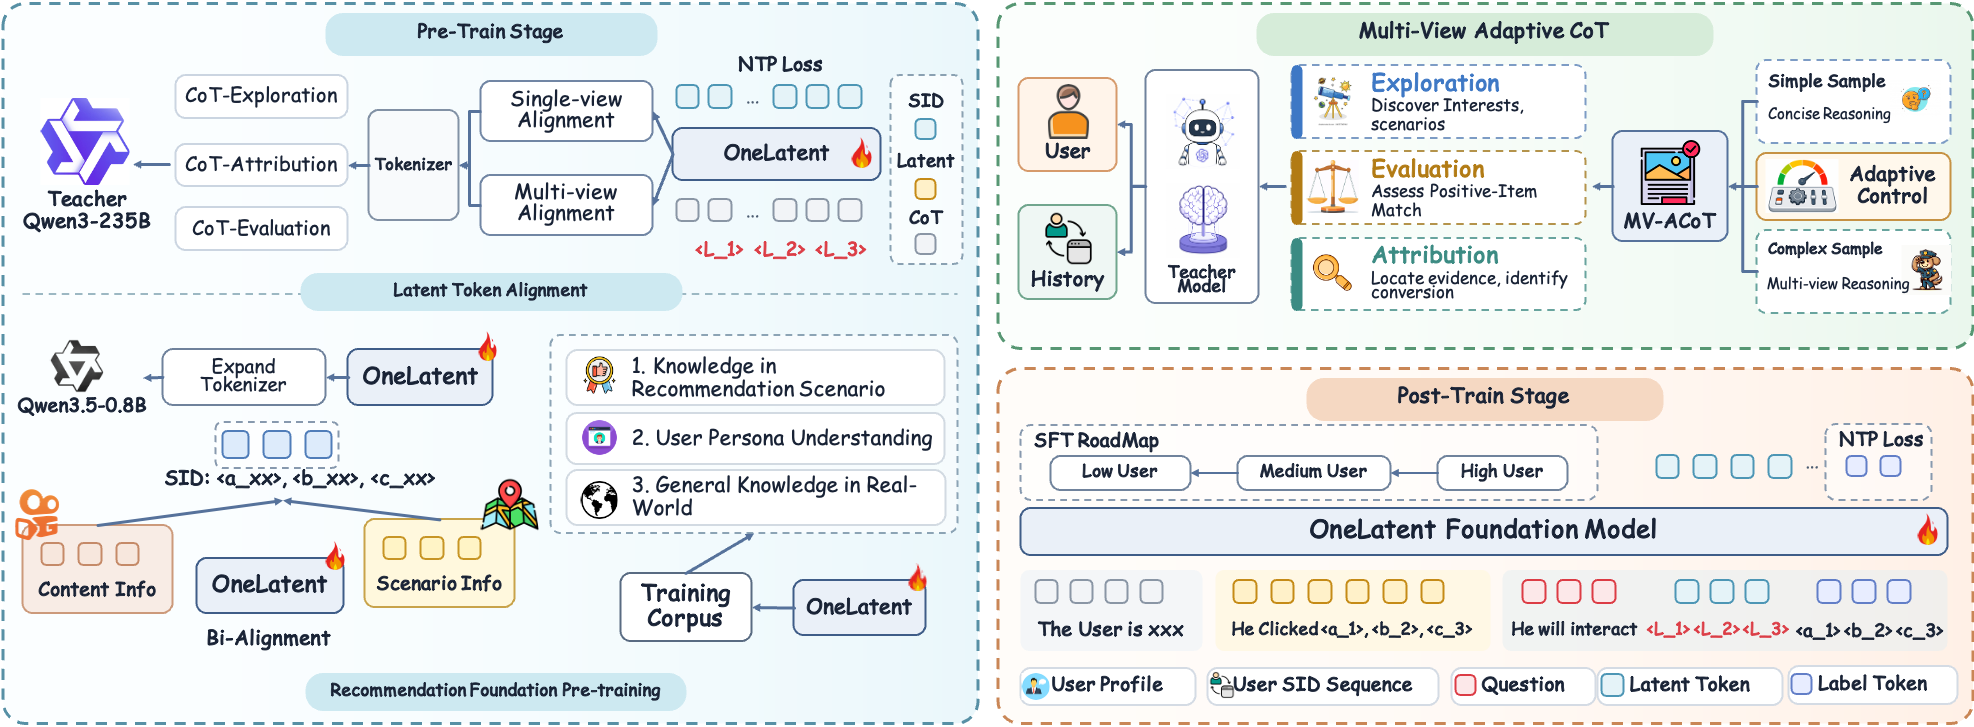
The authors' idea is to use the teacher's reasoning only as a training signal and keep the reasoning process in the model's internal hidden states, with no text output at inference.
2. Method
2.1 What the latent tokens are
The authors add 3 special tokens to the vocabulary, and all samples share this same set of token IDs. When the Transformer reaches these 3 positions it produces hidden states that vary with the context, and the SID tokens that follow read those hidden states through ordinary causal attention. There is no extra encoder, projection layer or decoder; the only added compute at inference is the fixed 3 tokens. The authors also state explicitly that later tokens can still see the raw context directly, so there is no guarantee that all the reasoning information is compressed into these 3 positions.
2.2 Teacher reasoning: three views, length adjusted to difficulty
The teacher model is Qwen3-235B-A22B-Instruct-2507, which writes reasoning for each sample from three views:
- Exploration: given only the user profile and history, the teacher infers the user's likely consumption intents and outputs reasoning plus a list of intents.
- Evaluation: additionally told the item the user actually interacted with, the teacher judges how well that item matches the user's evidence and outputs reasoning plus a score from 1 to 5.
- Attribution: told that this item is a positive sample, the teacher explains which historical signals led to the interaction.
The evaluation and attribution views use the true item, but this information goes only to the teacher and never enters the student model's input, so the answer does not leak. The prompt also asks the teacher to first judge how complex the evidence is: samples with a clear signal converge quickly, and samples with conflicting signals get a multi-dimensional comparison. The resulting reasoning drops to 65% of its original average length (taking the non-adaptive average length as 100), and on the longest tenth of samples the semantic similarity between the two kinds of reasoning is about 0.92.
2.3 Three-stage alignment and post-training
The student model is initialized from Qwen3.5-0.8B and first pretrained on the recommendation domain so that SIDs and item text descriptions can generate each other:
Here is the three-level SID of item and is its text description. The latent tokens are then trained in three stages:
- Stage I: the input is "profile, history, view marker, 3 latent tokens", and the target is to reproduce one view's teacher reasoning.
- Stage II: the same input, with the target changed to all of that sample's view reasonings. The loss of each reasoning is averaged over its tokens, so that long reasoning does not take a larger share of the loss.
- Stage III: the request context is added to the input, and the target changes from reasoning text to the SID of the next item.
Post-training first runs curriculum fine-tuning from high-activity to low-activity users, then trains on a 1:1 mix of "append latent tokens, then predict the SID" and "predict the SID directly without latent tokens", so that both modes remain usable.
3. Experiments
3.1 Main results
This experiment compares OneLatent with three groups of baselines: item-ID-based sequential recommenders (GRU4Rec, BERT4Rec, HSTU), SID-based generative recommenders (TIGER, OneRec), and reasoning-enhanced models based on OneReason. There are two datasets: 7 days of industrial logs from Kuaishou local services (test set of 20,393 instances), and Kuaishou's public LLM-Rec benchmark (test set of 10,000). The metric Hit@64 indicates whether the correct item appears among the top 64 results the model generates. The table below is taken from the paper's Table 2; NoThink and Think are the direct-answer and reason-first modes of the same checkpoint, and the parentheses give the reasoning data used for training:
| Method | Public SID@64 | Public ID@64 | Industrial SID@64 | Industrial ID@64 |
|---|---|---|---|---|
| TIGER | 0.0078 | 0.0156 | 0.1432 | 0.0859 |
| OneRec | 0.0082 | 0.0177 | 0.1468 | 0.0900 |
| OneReason | 0.0081 | 0.0272 | 0.1658 | 0.4941 |
| OneReason-CoT NoThink (original CoT) | 0.0104 | 0.0334 | 0.1823 | 0.4936 |
| OneReason-CoT NoThink (evaluation view) | 0.0213 | 0.0623 | 0.1962 | 0.5065 |
| OneReason-CoT Think (original CoT) | 0.0089 | 0.0305 | 0.1697 | 0.4759 |
| OneReason-CoT Think (three views merged) | 0.0091 | 0.0303 | 0.1505 | 0.4567 |
| OneLatent (three views merged) | 0.0239 | 0.0742 | 0.1993 | 0.5088 |
OneLatent is highest on every metric. But the source of the gain must be read from two separate comparisons. Against Think mode, industrial SID@64 is 17.44% higher; and when trained on the same three-view data, Think mode reaches only 0.1505 while OneLatent reaches 0.1993, which shows that for the same reasoning data, having the model write it out token by token before answering actually lowers accuracy, because the SID is generated only after the reasoning is finished and any error in the reasoning carries over to the SID. Against the strongest non-OneLatent result in each column, industrial SID@64 is only 1.58% higher and ID@64 only 0.45% higher; on the public data the gains are 12.21% and 19.10%. The strongest baseline on the industrial data is the model trained on evaluation-view reasoning that answers directly, and it already captures most of the gain.
On the 9B backbone, OneLatent reaches SID@64 of 0.2008, 8.13% above the best same-size non-latent result of 0.1857 (paper Table 3).
3.2 Inference efficiency
This experiment checks the inference overhead of the latent tokens. The authors compare three inference modes on 872 test instances (paper Table 7):
| Method | Total time (s) | QPS |
|---|---|---|
| Direct prediction (no reasoning) | 3.17 | 274.56 |
| Explicit reasoning | 55.59 | 15.68 |
| OneLatent | 3.17 | 274.29 |
OneLatent's throughput is 17.49 times that of explicit reasoning and nearly identical to direct prediction, because each request processes only 3 extra fixed tokens and does not need to decode reasoning text token by token. The paper's conclusion says "more than 10 times", which disagrees with the 17.49 times in the body; the number in the table is used here.
3.3 Quality and role of the teacher reasoning
This experiment checks whether the three-view reasoning is better than the original reasoning. The authors have GPT-5.5 score 100 samples of each kind of reasoning from 1 to 5 on nine dimensions (factuality, evidence use, causal logic and so on): OneReason's original reasoning averages 3.14, the adaptive-length reasoning 3.54, and the exploration, evaluation and attribution views 4.16, 4.33 and 4.03 (paper Table 4). Training OneLatent on different reasoning data raises public SID@64 from 0.0092 with the original reasoning to 0.0239 with the three views merged, and the evaluation view alone reaches 0.0233 (paper Table 5).
As the number of latent tokens goes from 1 to 3, the hit rates of all three SID levels rise; with 4 or 5 tokens they no longer improve consistently, so 3 are used in the end.
To see what is stored in the latent tokens, the authors feed the profile, view marker and 3 latent tokens to the trained model, deliberately leaving out the interaction history, have it generate reasoning text, and compare its semantic similarity with the teacher's reasoning; the cosine similarities of the three views are between 0.79 and 0.80 (paper Table 8). The authors themselves note that the profile is still visible, so this similarity only shows an association and cannot prove that the reasoning information is all stored in the latent tokens.
3.4 Deployment and A/B test
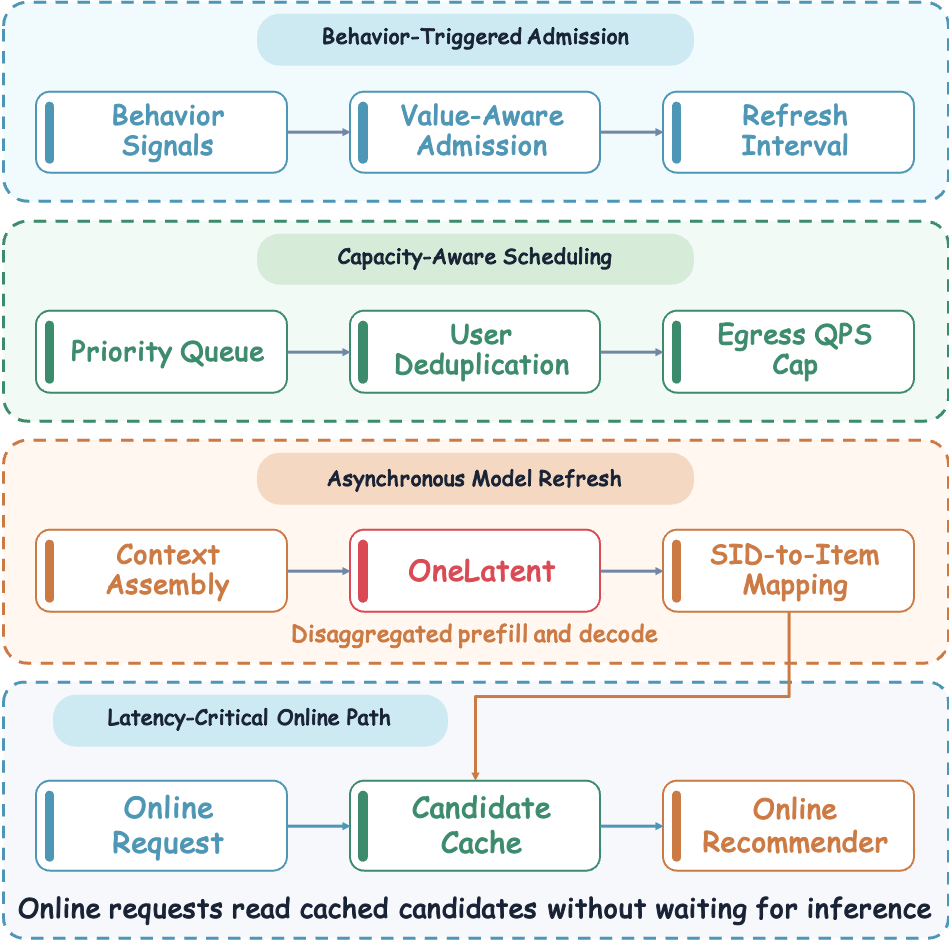
Even without reasoning text, calling the foundation model synchronously for every request still exceeds the latency and throughput budget. OneLatent is therefore deployed as a separate retrieval channel: new user behavior triggers asynchronous inference, refresh priority is set by user value and behavior strength, the generated candidates are written to Redis, and online requests take candidates from the cache, where they compete with the existing retrieval results in fine ranking. The A/B test ran in a sub-scenario of Kuaishou's local-services advertising, with 5% of traffic each for the treatment and control groups, from September 3 to 10, 2026. The treatment group's impressions rose 2.566%, ad spend rose 5.157%, and the posterior estimate of revenue rose 9.6%.
4. Limitations
The paper has no separate limitations section; in the body the authors acknowledge two points: the latent tokens are not a strict information bottleneck, and the reasoning information may be spread across the whole model; and the gain in Table 6 comes from the complete training pipeline and cannot be attributed to the latent tokens alone.
Two further points deserve attention. First, on the industrial data OneLatent is only 1.58% above the direct-answer model trained on the same teacher data, and the paper reports no variance across runs, so it is impossible to judge whether this gap is stable. Second, the online deployment uses an asynchronous cache, with candidates generated after the user's last behavior; the paper does not separate how much of the A/B gain comes from latent reasoning and how much from adding one more retrieval channel.
5. Practical implications
First, to give a recommendation model reasoning ability, the teacher's reasoning can first be used as training data rather than requiring the model to generate reasoning online. In the paper, the same three-view reasoning data reaches industrial SID@64 of 0.1993 when used as a training signal, but only 0.1505 when the model must write it out before answering.
Second, when evaluating "latent reasoning" methods, include a direct-answer model trained on the same teacher data as a baseline. On the industrial data in this paper, most of the gain already appears in that baseline, and comparing only against explicit reasoning overstates the effect of the latent tokens themselves.