 RecSys 2026
SHARE

The Google Discover ads team iterates on models in three steps: compare the loss of the new and old models offline, run a small-traffic A/B to see the value delivered to advertisers, and finally bundle the changes that pass into a large-traffic launch. The old problem was that these three steps did not line up: the correlation between the change in the conversion model's (pConvs) offline Poisson loss and online value was only 0.1, and many changes that looked better offline failed in the small-traffic stage; the correlation between small-traffic and large-traffic results was only 0.53. This paper (RecSys 2026 Best Industry Paper) fixes both ends: the offline loss is weighted by how much each click is worth to the advertiser, so that a loss decrease corresponds to a value increase; on the experimentation side, systematic biases and noise are removed one by one. After the changes, the offline-to-online correlation rose to 0.65 and small-to-large traffic to 0.93, switching two models to the new objective raised online value by 4.7% in total, and the authors estimate that R&D efficiency roughly doubled.
1. Three stages, three kinds of error
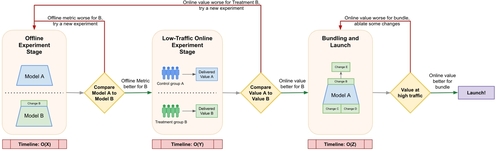
The auction ranking stage has two models: pCTR predicts the click after an impression, pConvs predicts the number of conversions after a click; together with the advertiser's bid they produce the auction score for a second-price auction. The business metric behind launch decisions is Delivered Value (DV):
is the target price per conversion the advertiser is willing to pay (tCPA), is the number of conversions from the -th click. A purchase of a 1,000-dollar mattress is worth more than a hundred visits to a merchant's website, yet an ordinary conversion prediction loss counts both as equal conversions.
The stages take O(X), O(Y) and O(Z) time respectively, with X much smaller than Y and Y much smaller than Z, so every wrong judgment in an earlier stage wastes the more expensive resources of later stages. The authors split measurement error into three kinds: objective misalignment (what an earlier stage measures does not predict the later stage's result), systematic error (bias introduced by the experimental setup), and random error (variance from system noise).
2. Aligning the offline loss with delivered value
2.1 pConvs: Poisson loss weighted by tCPA
pConvs originally did maximum likelihood under a Poisson distribution, with the Poisson loss (PL) , where is the predicted number of conversions for the -th click. The model's output does not change: it still predicts conversions per click. What changes is the loss, which multiplies each click by the advertiser's value per conversion , giving the weighted Poisson loss (WPL). Mistakes on high-value clicks now cost more, so the model is effectively fitting delivered value rather than conversion counts:
The paper gives a derivation for why the weighting is correct. Let the advertiser's true value be , the bid , and the second price (what the advertiser actually pays) have density ; the expected profit of one auction is the integral of "value minus cost" over winning outcomes, . If , the integral comes out as plus a constant, so maximizing profit is equivalent to minimizing ; substituting and back and dropping parameter-independent constants gives WPL. Poisson regression works here not because conversion counts really follow a Poisson distribution, but because the 1/s cost distribution approximately holds.
2.2 pCTR: from "whether clicked" to "how many clicks"
pCTR originally predicted the probability that an impression is clicked at least once, trained with log loss and evaluated with AUCLoss (1 minus AUC). A carousel ad impression often gets several clicks, and each extra click has value, so the team changed the target to the expected number of clicks per impression, raising online DV by 1.2%.
This change is almost invisible offline:
| Offline metric | Change |
|---|---|
| Binary AUCLoss | -0.10% |
| Multi-class AUCLoss | -0.15% |
| LL | +0.08% |
| PL_CTR | -0.21% |
Log loss even got worse; only the Poisson loss computed on click counts, PL_CTR, dropped clearly, matching the direction of the 1.2% online gain.
pCTR also needs to carry value, but using conversion value directly as the weight fails because too few clicks have conversions and the labels are an order of magnitude sparser. The authors instead use expected delivered value (EDV) as a proxy: for every actual click, multiply the value per conversion by the pConvs model's predicted conversions and sum, . The pCTR model trains on every impression, clicked or not. Each impression is weighted by an estimate of the value one click would bring: the ad's value per conversion times the pConvs model's predicted conversions per click , shared by all clicks in that impression, giving , where is the number of clicks on the -th impression. The appendix uses the assumption that the runner-up's effective cost-per-thousand-impressions bid follows a distribution to give a derivation of the same form as 2.1.
2.3 Results after switching objectives
This experiment is meant to show two things: WPL as an offline metric better predicts online value, and training on WPL directly raises value.
| Model | PL change | WPL change | Online DV |
|---|---|---|---|
| pConvs trained on WPL | +0.1% | -0.35% | +3% |
| pCTR trained on WPL | +0.03% | -0.04% | +0.5% |
For both models PL got worse, WPL got better, and online DV went up, which shows that what PL measures points in a different direction from the business objective.
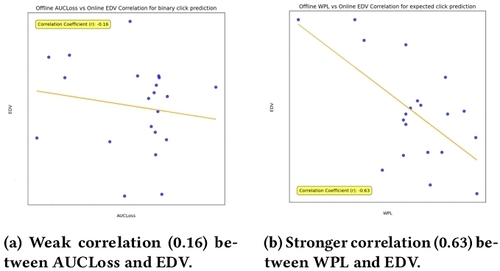
The authors measure how good an offline metric is by correlation: over the same set of changes, compute the Pearson correlation between the change in the offline metric and the change in online DV (absolute values are reported below). For pConvs, over about 40 experiments with online data, the old PL is almost uncorrelated with online value (0.1), while WPL reaches 0.65 and stays around 0.69 on later new experiments, which shows the result was not picked after the fact. pCTR is similar: the original AUCLoss and log loss are essentially uncorrelated with online value (0.16 and 0.09), and after switching to expected clicks and evaluating with , the correlation rises to 0.63.
3. Offline stage: systematic and random error
All models are trained continuously online, each example passes through only once, and offline evaluation uses progressive validation: each example is first predicted and its loss recorded, then used for training.
Systematic error has two sources. The first is label maturity bias. Conversion labels arrive with delay, and the experiment model starts later than the control, so while catching up on historical data it sees more complete conversion labels. Its loss over the same time period then looks better only because it has more information. The fix is to compare only over periods where the two models' training data have the same quality. The second is optimizer and architecture artifacts. Architectures like DLRM first split features into groups and then let features interact within a group. Adding even one constant feature, which carries no information, can shift the grouping and split important features that need to interact into different groups, causing a systematic regression. The paper also lists second-order optimizers as a source of such artifacts but does not explain how they cause it; the authors' remedy is one principle: in architectures that group features, watch whether correlated features end up in the same group. The paper gives no concrete procedure. After fixing these two, the offline difference between two equivalent models stays within 0.02%, where previously significant differences were often measured.
Random error is suppressed by standardizing the measurement method. The table below compares, over 25 pConvs experiments, the offline-online correlation and the AUC-ROC of using the offline result to judge whether the online result is good, when the offline metric is measured over different time windows. is each experiment's launch time.
| Offline measurement window | Correlation | AUC-ROC |
|---|---|---|
| [T−6 months, T−3 months] | 0.650 | 0.760 |
| [T−1 month, T] | 0.577 | 0.690 |
| [T−1 week, T] | 0.01 | 0.489 |
| Same fixed 3 months for all experiments | 0.640 | 0.755 |
| [T, T+online experiment duration] | 0.604 | 0.736 |
Looking only at the last week, offline results have almost no predictive power: the correlation is close to 0 and AUC-ROC is even below 0.5, worse than random guessing; a 3-month window beats a 1-month one, because the longer the window, the more random noise averages out. WPL weights range from a few cents to over a thousand dollars and are very noisy. So during measurement the weights get an upper limit, with anything above it counted at the limit; the limit matches the one used for DV capping below (the paper does not publish the value), which halves the confidence interval without introducing bias.
4. Online stage: the small-traffic control must be as small as the experiment
4.1 Systematic error comes from different traffic sizes
The common practice is to compare the small-traffic experiment model against the large-traffic production model, which is necessarily biased. There are three reasons. The first is the winner's curse. In an auction, ads whose value is overestimated are more likely to win, and a model corrects this bias in continuous training from the impressions and conversions its own winning bids bring back. A small-traffic model wins few impressions with its own bids, so it lacks the feedback to correct itself; a large-traffic model has plenty of such data. The second is budget. A campaign's budget is fixed and does not scale with experiment traffic. Take a campaign with a $100 budget that the experiment nearly exhausts at small traffic. At large traffic the impressions grow but the budget is still $100, so the extra impressions cannot be bought and the gain seen at small traffic shrinks. Small traffic therefore overestimates value. The paper notes that parallel split-budget experiments can mitigate this but are not practical. The third is feedback loops. At large traffic, feedback loops keep correcting deviations in predictions so that delivery meets its target constraints. At small traffic the data are too sparse, and running a separate feedback loop would hurt, so this correction is missing. The paper does not say which metrics the target constraints refer to.
The authors' approach is to set a standard small-traffic size and retrain a copy of the production model at that traffic size, as a shared control for all experiments of that size. When another traffic size is needed, a separate control of that size is trained. After the change, the DV difference between two identical retrained models is close to 0%, where it used to often exceed 1%.
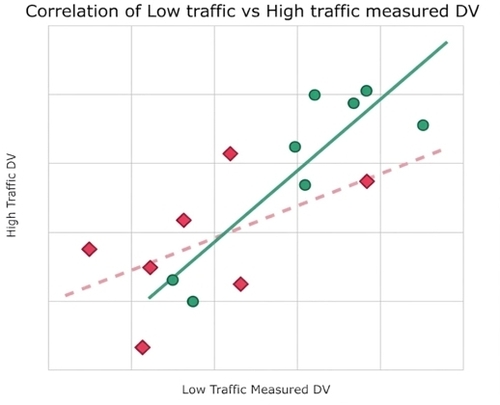
This comparison uses 7 historical experiments (old setup) and 8 new experiments (new setup); the small-to-large traffic correlation rose from 0.53 to 0.93. The sample is small because large-traffic experiments are expensive, but each large-traffic experiment runs long with a lot of traffic, so each single measurement is itself precise. The two correlations, 0.53 and 0.93, cannot be compared as independent measurements: the paper says both setups evaluate the same underlying models, so the two sets of measurements are themselves correlated, at about 0.75. The paper does not say how the 7 and 8 experiments correspond or how the 0.75 was computed. The authors compare the two dependent correlations with a Williams t-test and find the rise from 0.53 to 0.93 significant (p<0.05).
4.2 Random error: capping and expected values
DV depends on sparse conversions, so its confidence interval is wide, and the authors narrow it in two ways. First, capping per-click values shrinks the interval width by 40%. Second, replacing actual DV with expected DV (pConvs predictions in place of actual conversions) shrinks the width by 70%. Both move the measured DV away from its unprocessed value; the paper's Table 5 lists this cost as under 3% and about 5% without saying what the percentages are relative to, and the text says the effect on metric bias is marginal. Combined, a 2%-traffic experiment reaches the precision of a former 30%-traffic experiment, so the same traffic can run more experiments in parallel.
5. Why correlation determines efficiency
The authors assume that offline and online results follow a correlated bivariate normal distribution; multiplying the probability that the offline judgment agrees in direction with the next stage by the probability that the small-traffic judgment agrees with large traffic gives the probability that both judgments are correct:
is the offline-to-small-traffic correlation and the small-to-large traffic correlation. With the pre-improvement values, the probability that both judgments are right is only about 0.36, meaning most changes were misjudged at one step or the other; with the post-improvement values, it rises to about 0.65.
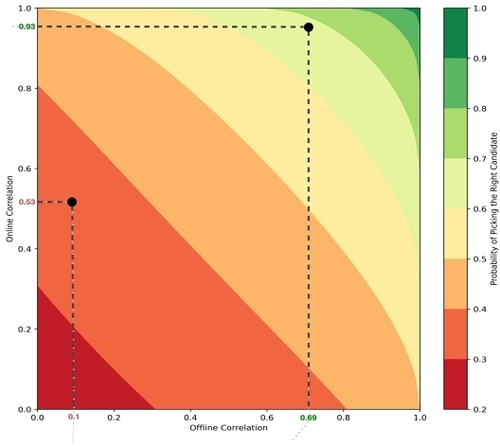
The text gives the improved offline correlation as 0.65 while the figure marks 0.69, but by the formula the two correspond to probabilities only about 0.01 apart, so the conclusion is unaffected. The paper's efficiency evidence is 100+ experimental changes over 3 years: the number of successful changes included in each bundled pConvs launch, and the number of changes per contributor, both kept rising. The authors estimate overall efficiency roughly doubled, with exact numbers withheld for confidentiality.
6. Limitations
The authors acknowledge that all evidence comes from a single continuously trained online environment, Google Discover ads. The WPL derivation relies on costs following a distribution; the authors note in the appendix that the actual runner-up bid distribution decays faster with a lighter tail, and leave cost distributions closer to reality for future work.
In addition, DV itself is a simplified metric the paper uses to illustrate the problem; real launches look at several interdependent metrics, and the small-to-large traffic correlation is based on only 7 and 8 experiments.
7. Practical implications
- If your model serves an auction ranked by bids, try multiplying the offline evaluation loss by each example's business value and check whether its correlation with online results improves; without changing training, this tells you whether your current offline metric is measuring the wrong thing.
- A small-traffic experiment's control should be the same size and retrained the same way as the experiment arm. Comparing a small-traffic experiment arm against the large-traffic production model mixes winner's curse, budget and feedback-control biases into the measured difference, and an A/A experiment can catch this first.
How did this read for you?
Hoot made a note. Thanks for the feedback.

One tap, no sign-in; tap again to undo. Only anonymous counts are kept, never who you are.
Discussion
Add experiment details, reproduction notes or a different take. Requires a GitHub sign-in.
Loading the discussion…