LLM training throughput hinges on the recipe—sharding, memory–compute trade-offs, kernels and overlap—and that recipe changes with every model, accelerator and framework. Fixed-knob tuners only check that a job runs, miss levers outside the preset space, and can silently change training semantics. Amazon’s ATTUNE is a coding agent that retunes any working recipe unattended inside a GPU-hour budget. On H100/H200/B200 it lifts throughput 1.7× on average (up to ~3.9×) and beats four NVIDIA AutoModel published recipes by 6–17%; on held-out models it improves recipes written for another setting by up to 2.6× (MiniMax-M2). Throughput gaps often live outside the fixed knob space—letting a coding agent edit the recipe beats grid search.
1. Problem
Bayesian/grid tuners search preset knobs for “runs.” Missed throughput often sits in recipe text (expert capacity, overlap, kernels). ATTUNE searches by editing code/config.
2. Method
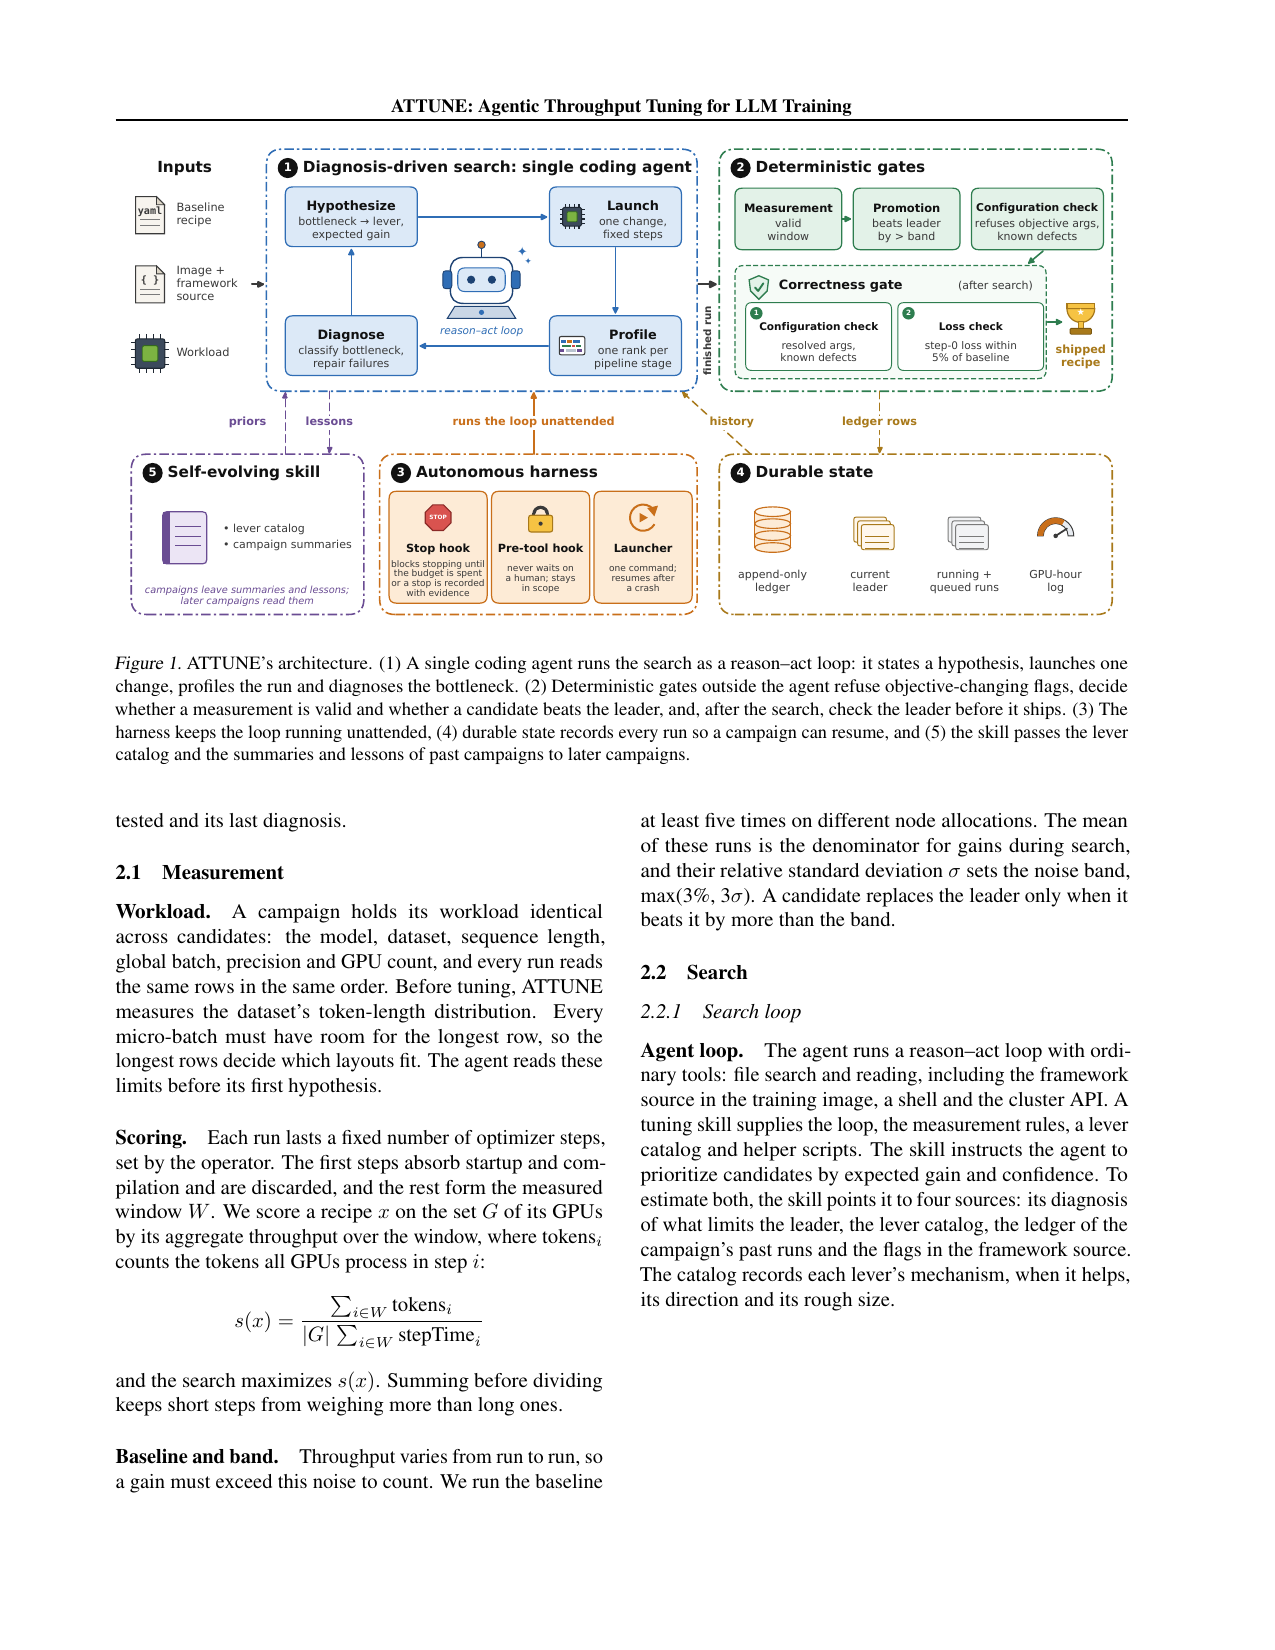
One agent runs a reason–act loop: hypothesize → one change → profile → diagnose. Deterministic gates outside the agent refuse objective-changing flags, validate measurements, and decide whether a candidate beats the leader; a final consistency check follows. Budget is capped in GPU-hours.
3. Core claim
Tuning becomes recipe editing with gates that block silent training changes. Editable recipe text vs immutable training semantics—gates separate the two.
4. Experiments
Mean +1.7× (peak ~3.9×) vs replaced recipes; +6–17% vs AutoModel published numbers; held-out MiniMax-M2 up to +2.6×; beats automated tuners including Bayesian opt under the same GPU-hour budget.
5. Limits
Needs a working seed recipe and parseable profiles; gate rules track framework versions; throughput ≠ unchanged loss curves.
6. Practice
Hang recipe agents on new-model×new-cluster onboarding behind a gate allowlist and a GPU-hour cap.